Predictable Fabric Costs, Predictable AI: Capacity Unit Economics with agenTriniti℠


If you’ve ever sized a Microsoft Fabric capacity by picking a number that “seemed about right,” you’re not alone. Most teams still approach Fabric capacity planning the same way they approached traditional cloud infrastructure: start with an estimate, go live, and adjust later if costs climb or workloads slow down.
The problem is that Fabric doesn’t work like traditional infrastructure. Capacity Units (CUs) are a shared resource across every workload running on that capacity, including Spark, Data Warehouse, Power BI, and Data Factory pipelines. When one workload spikes, it can eat into the headroom available to everything else. Size for the warehouse alone and you may find your Power BI refreshes throttled during month-end close. Size for everything separately and you’re probably paying for capacity you don’t need.
This is the exact problem Capacity Unit Economics, a cost-forecasting framework used to size Fabric capacity before migration, is built to solve. Instead of estimating capacity based on assumptions, it looks at how your existing environment is actually used, translates that usage into expected CU consumption, and identifies an appropriate F-SKU before you commit to long-term capacity spend.
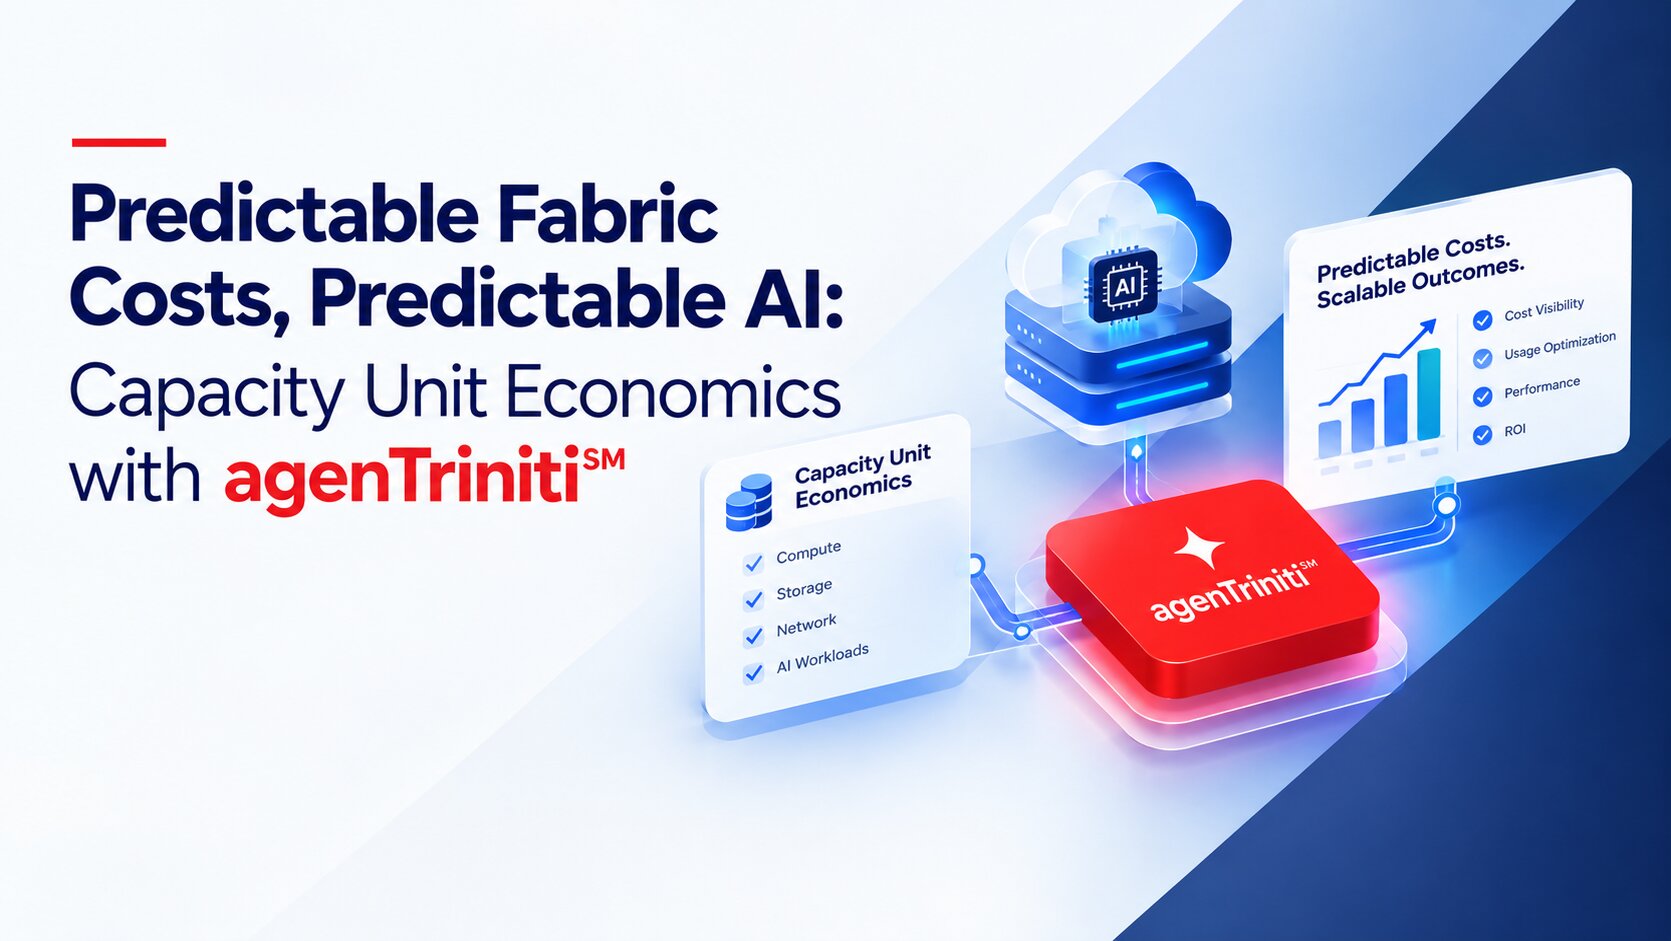
Capacity Unit Economics follows a simple chain of logic:
Current workloads → Workload Profiler → CU Prediction Model → Right-sized F-SKU
The framework captures how your warehouse queries, ETL jobs, and BI refreshes behave today, simulates how that combined demand would land on different F-SKU tiers, and recommends a capacity backed by an actual budget projection rather than a guess.
The key insight is that capacity planning can’t focus on a single workload. The real question is: what will the combined CU demand look like once every major workload shares the same capacity? Answering that before migration turns capacity sizing from trial-and-error into a planned, budgeted decision.
Two components do the heavy lifting.
The Workload Profiler examines your existing environment and pulls together warehouse query activity, ETL job runtimes, and BI refresh schedules. It builds a picture of what runs, how often, how much load it generates, and where different workloads overlap in time.
The Simulation Engine takes that profile and maps it against Fabric’s published CU consumption rates for each engine. It then tests F-SKU options from F2 through F2048 and estimates utilization, available headroom, and burst risk for each one.
You don’t need a separate infrastructure setup to run this. Access to existing platform logs plus a Fabric trial or pay-as-you-go capacity is usually enough to validate the model against real consumption. Because the profiler and simulation engine can run as scheduled notebooks against a Fabric Lakehouse, the output becomes a reusable, auditable dataset instead of a one-time spreadsheet exercise.
There’s no separate license attached to this. Capacity Unit Economics is a methodology and analysis layer that runs on top of your existing telemetry and Fabric’s published CU rates. The financial benefit comes from avoiding two expensive mistakes: over-provisioning capacity you’ll never use, and under-provisioning capacity that leads to throttling mid-migration.
There is real upfront effort involved. Someone has to pull clean usage logs, validate the model against a trial capacity, and get budget owners to sign off on the recommendation. But that effort is designed to prevent bigger delays later, like mid-migration resizing, emergency capacity changes, or a surprise budget review after the first invoice lands.
Profile extracts volume, frequency, and concurrency from existing platform logs, flags overlapping peak windows across engines and teams, and re-profiles automatically as workloads evolve.
Predict simulates the workload profile against every candidate F-SKU, projects utilization and burst risk per scenario, and surfaces a recommended SKU with a documented confidence range.
Provision turns that recommendation into a purchase with budget sign-off attached, sets autoscale and surge-protection guardrails from day one, and tracks actual versus predicted consumption after launch.
The Profiler itself is a lightweight notebook. It reads existing query and job history and converts it into a time-series view of demand, with no agents to install and no changes to how workloads currently run. Once an F-SKU is chosen, that same profile becomes the baseline for an ongoing “actual vs. predicted” dashboard, turning sizing from a one-time exercise into continuous monitoring.
Sizing isn’t just about landing on a single number. It means balancing peak demand, budget limits, and growth headroom, and Capacity Unit Economics makes that trade-off explicit through a fixed decision path:
Simulated peak CU → Exceeds smallest viable SKU? → Within budget ceiling? → Headroom for 6-12 months of growth? → Approve SKU
Because simulation results are stored as structured data rather than buried in a slide deck, the sizing decision can be reviewed, audited, and revisited. If the workload mix changes, the simulation reruns against the updated profile instead of waiting for the next budget cycle to catch the impact.
A good F-SKU recommendation is only half the job. The other half is making sure real consumption stays inside the modeled envelope once the capacity is live. Administrators can configure surge-protection and autoscale policies at the capacity level, while workspace usage gets monitored against the same CU baseline the simulation produced.
FinOps teams get a single modeled baseline to check actual consumption against through the Fabric capacity metrics dashboard, instead of reconciling separate invoices and utilization reports for every workload sharing the capacity.
Pattern A: Steady-state BI refreshes. Scheduled nightly refreshes produce a flat, predictable CU draw, which usually points to the smallest viable F-SKU.
Pattern B: Spiky batch ETL. Bursty month-end batch jobs need simulated burst scenarios, which usually point to a baseline SKU plus an autoscale buffer.
Most enterprise environments land somewhere between these two extremes, especially once month-end finance workloads start sharing a capacity with daily BI refreshes. That’s exactly why the framework simulates the combined workload rather than sizing each piece in isolation.
| Capability | Traditional Sizing | Capacity Unit Economics |
| Sizing basis | Vendor recommendation or rough estimate | Simulated CU demand from real workload profiles |
| Budget predictability | Confirmed only after first invoice | Projected before capacity is purchased |
| Throttling risk | Discovered in production | Modeled across peak-overlap scenarios |
| Growth planning | Reactive resize when limits are hit | Headroom built into the initial SKU choice |
| Governance | Single negotiated number | Fixed decision path, logged per SKU decision |
| Cost ownership | Reconciled after the fact | Tracked live against a modeled baseline |
| Rework on mis-size | Emergency SKU upgrade mid-migration | Re-simulate and adjust before go-live |
| Best fit | Small, single-workload capacities | Shared capacities with multiple overlapping engines |
Capacity Unit Economics gives you an estimate, not a guarantee. Fabric’s CU consumption rates and F-SKU pricing can change over time, and the model is only as good as the usage data feeding it. Treat the output as a practical, evidence-based starting point, and validate the recommendation on a trial capacity before making a long-term commitment.
For delivery teams, it means having a data-backed F-SKU recommendation before any workspace migrates, which cuts down on last-minute resizing conversations and leaves a baseline for post-launch monitoring.
For advisory conversations, it gives sponsors a real answer to the first question they usually ask about a Fabric business case: what is this going to cost? Instead of a vendor quote, you get a workload-specific projection based on actual usage.
For the broader program, it reframes migration planning. The question stops being which SKU to pick from a price list and becomes how your workloads will behave once they’re sharing compute. Getting ahead of that interaction is what prevents surprise costs after go-live.
A good starting point: pick one representative domain, profile its existing workload, and simulate it across three candidate F-SKUs. Compare the model’s prediction against actual usage on a short-term Fabric trial capacity, then use the results to fine-tune the approach before rolling it out across the full migration.
In this context, Capacity Unit Economics can serve as a capacity-planning component within the agenTriniti Package ai agent lifecycle, extending the framework from traditional Fabric workloads to validated AI workload scenarios. That fixed-price model only works if the underlying Fabric capacity is sized correctly before an agent goes live, which is exactly the gap Capacity Unit Economics is built to close.
Run the Profile, Predict, Provision cycle during the Build phase, before committing to an F-SKU, and the fixed-price engagement gets built around a validated cost baseline instead of a rough estimate. That matters more once AI agents are in the mix: AI workloads can introduce additional Fabric capacity demand through activities such as data retrieval, orchestration, processing and other Fabric-based operations. Where AI workloads run on or depend on Fabric capacity, these activities should be included in the combined workload profile and validated through actual capacity consumption. Sizing for that combined demand up front means the capacity underneath agenTriniti is right-sized from day one, not resized after the first agent hits production.
It also carries into Manage: the same actual-versus-predicted dashboard used for cost governance doubles as an early warning system if new agent workloads push consumption past what was modeled, so the “Continuously Upgrade” part of the package has real usage data to work from instead of a guess.
Fabric capacity planning doesn’t have to be a guessing game that gets corrected after the first invoice. Capacity Unit Economics gives you a way to model combined workload demand before migration, so the F-SKU you choose is backed by real usage data instead of a rough estimate.
The payoff shows up twice: once during migration, when you avoid emergency resizing and throttling surprises, and again after go-live, when your team has a documented baseline to track actual consumption against. Start small, validate the model on a trial capacity, and use what you learn to scale the approach across the rest of the migration.
If you’re planning a Fabric migration and want help sizing capacity before you commit to a spend, get in touch with the Airo Digital Labs team to walk through a pilot on one of your workloads.
Capacity Unit Economics is a cost-forecasting framework for Microsoft Fabric that predicts and controls capacity costs before migration. It profiles existing workload usage, simulates that usage against different F-SKU options, and recommends a right-sized capacity backed by a budget projection instead of a guess.
Because Fabric Capacity Units are shared across every workload on that capacity, including Spark, Data Warehouse, Power BI, and Data Factory. Increased activity in one workload can reduce the capacity available to others, so sizing has to account for combined demand rather than one workload at a time.
An F-SKU is a Fabric capacity tier, ranging from F2 up to F2048, that determines how many Capacity Units are available for workloads to consume. Choosing the right F-SKU means balancing expected peak demand against budget and future growth.
No. It’s a methodology and analysis layer that runs on existing platform logs and Fabric’s own published CU consumption rates. The profiler and simulation engine can run as scheduled notebooks against a Fabric Lakehouse, so no new licensing is required.
By tracking real consumption against the modeled baseline from the simulation, using surge-protection and autoscale guardrails at the capacity level, and monitoring workspace usage against that same baseline through the Fabric capacity metrics app.
No. It’s an estimate based on current usage patterns and Fabric’s published consumption rates, both of which can change. It should be validated on a trial or pay-as-you-go capacity before committing to a long-term F-SKU purchase.
